> ## Documentation Index
> Fetch the complete documentation index at: https://praison.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Metrics
> Track token usage and cost metrics for agent executions
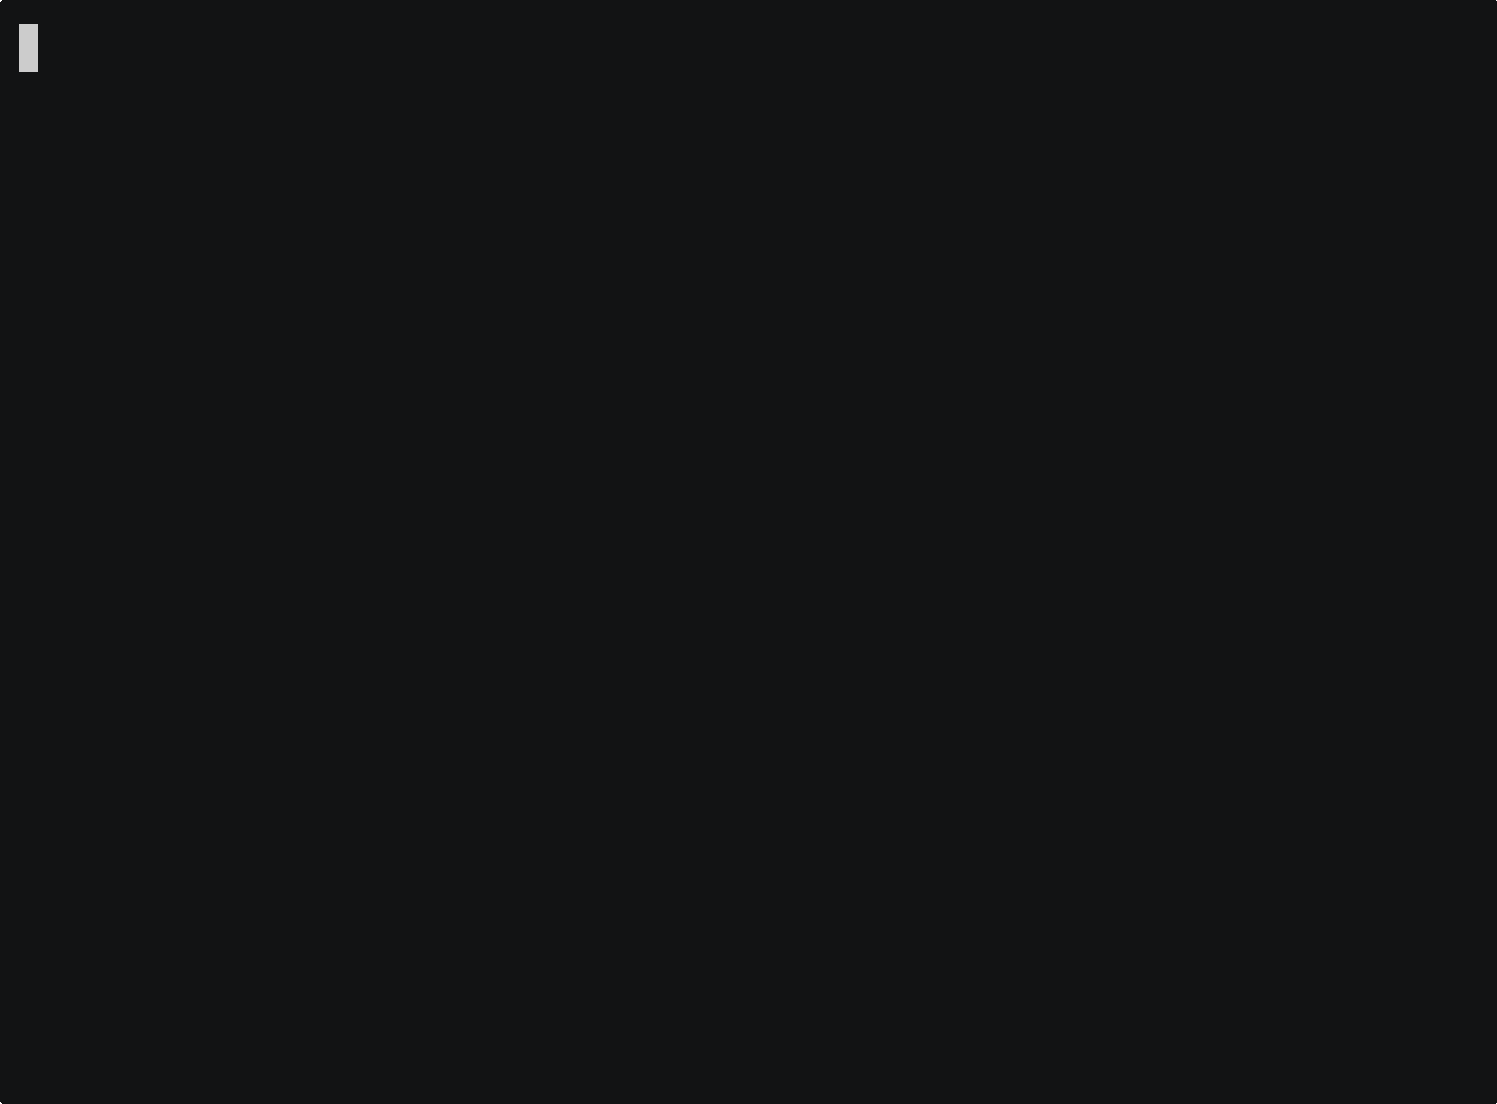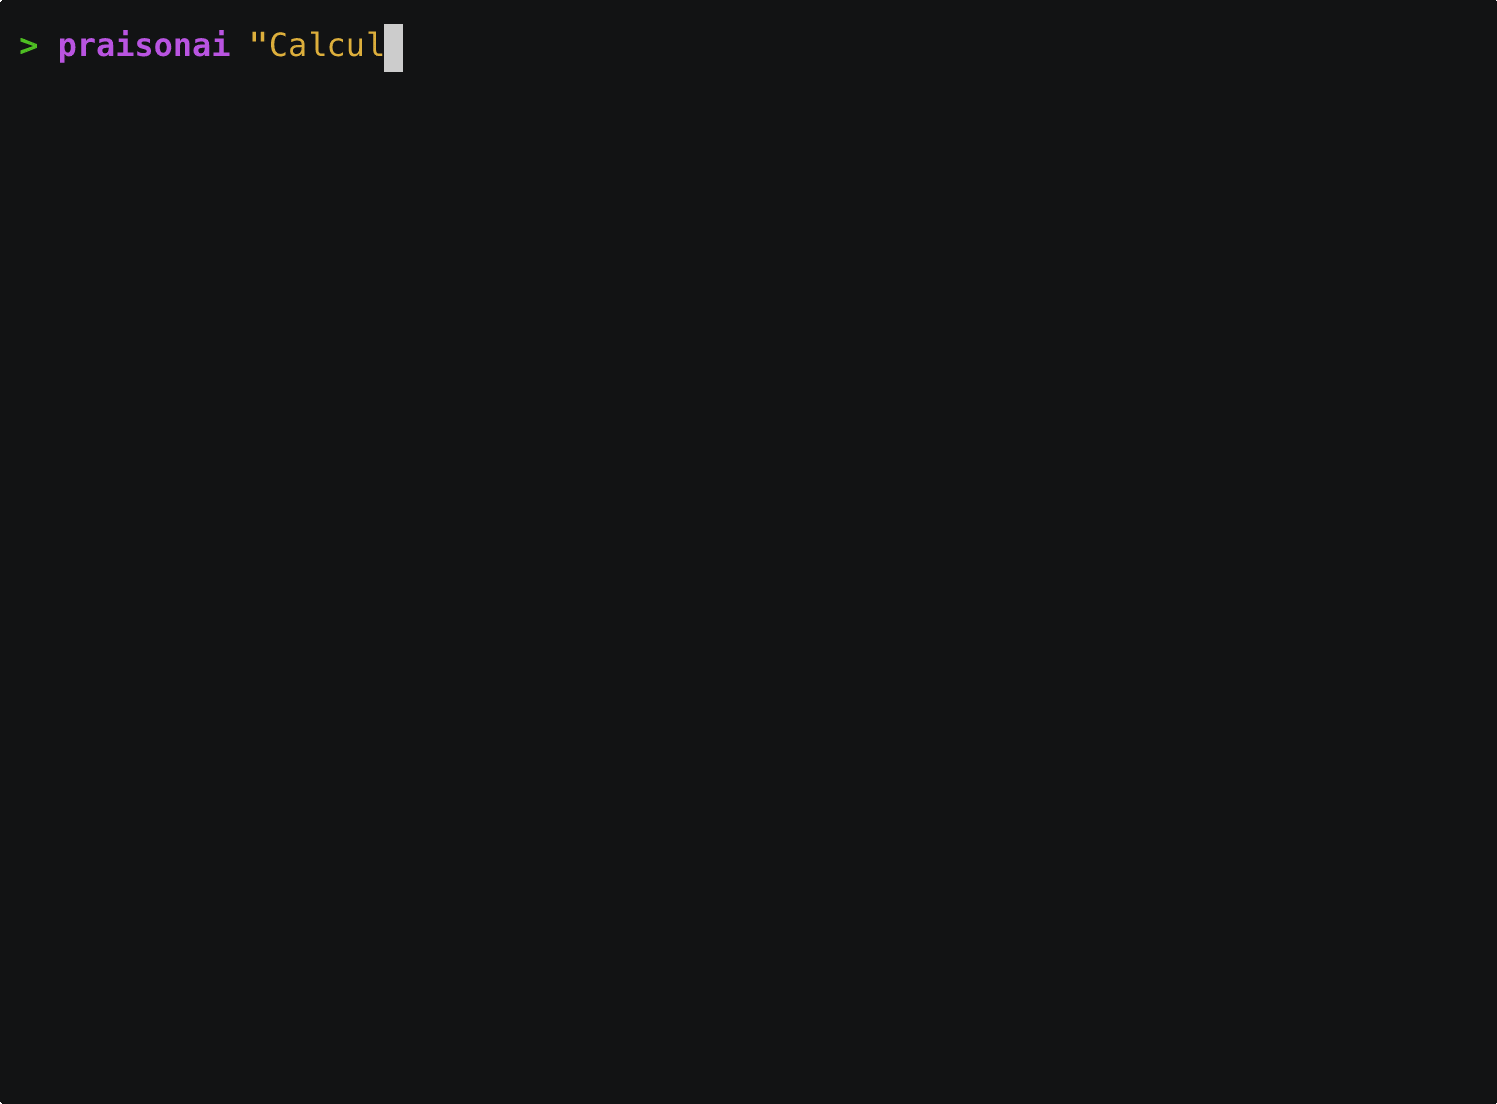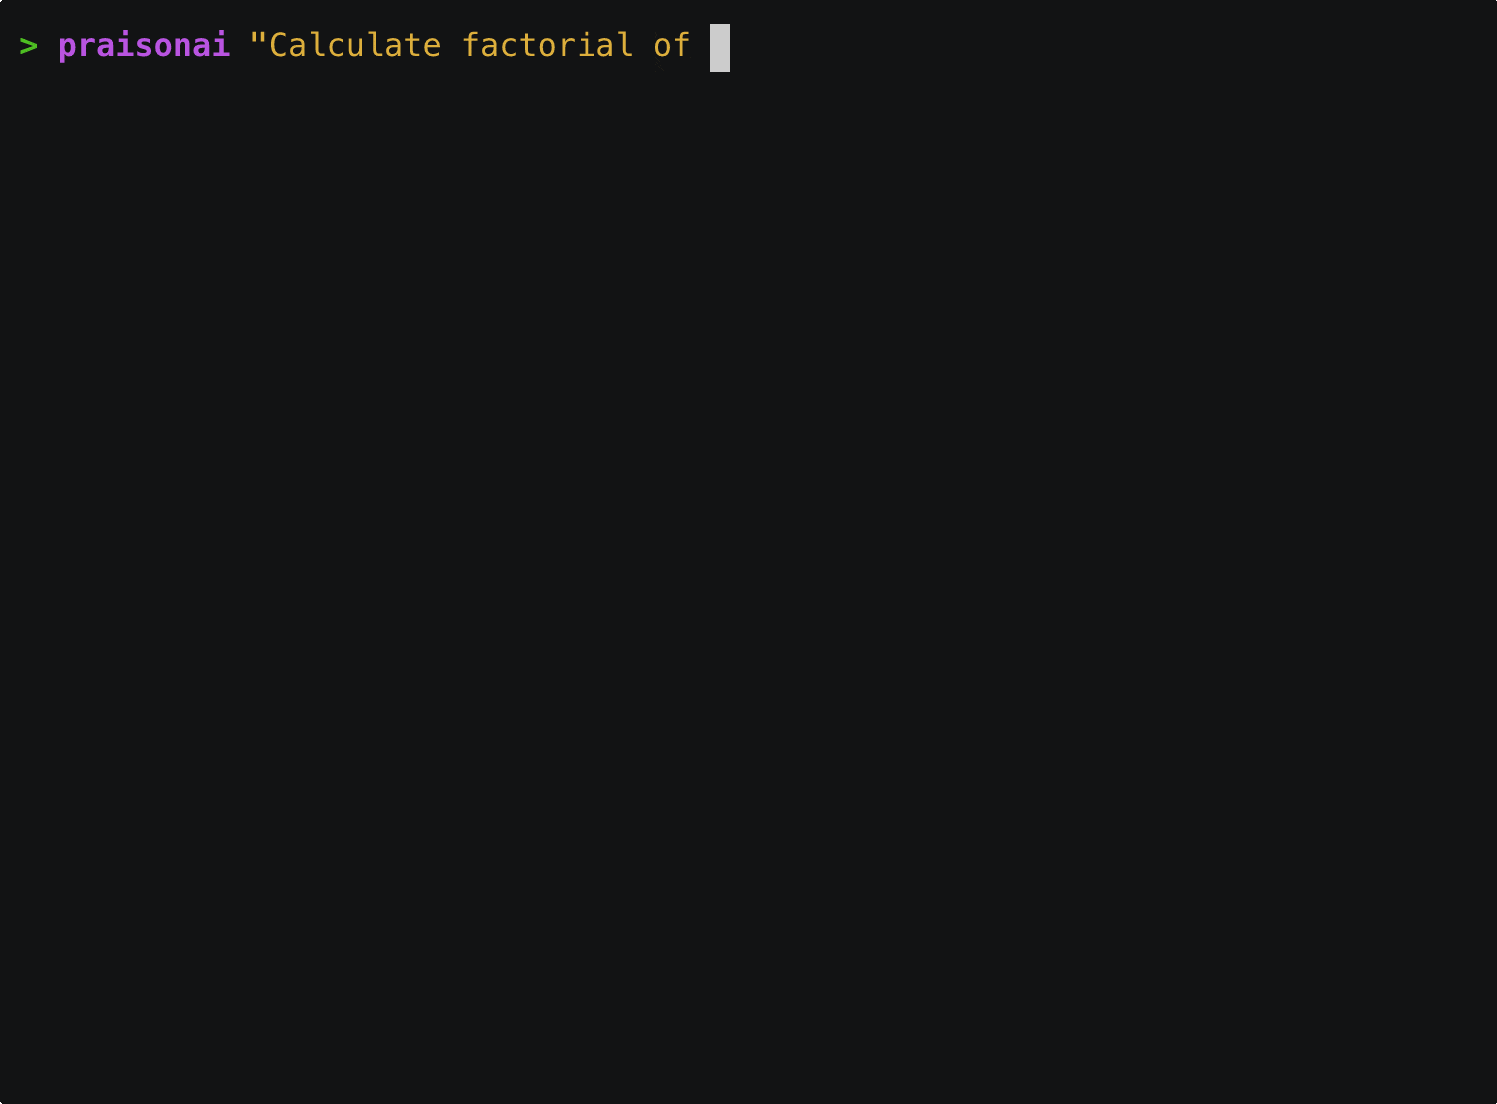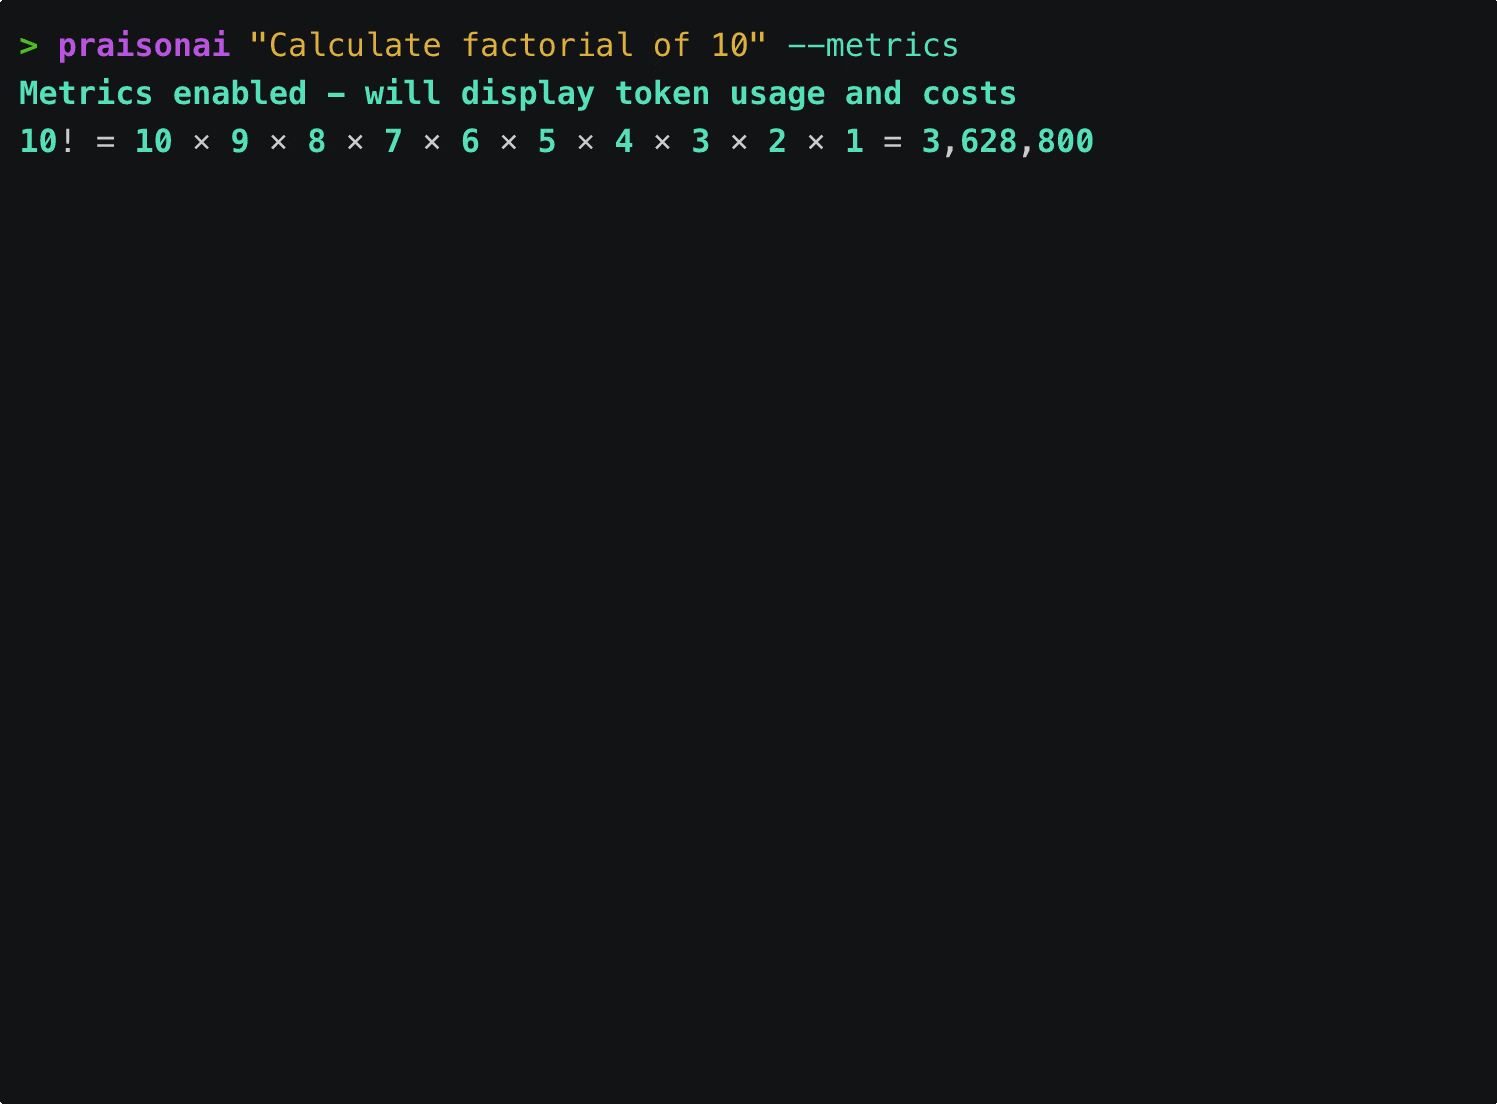
The `--metrics` flag displays token usage and cost information after agent execution.
## Quick Start
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
praisonai "Analyze this data" --metrics
```
 ## Usage
### Basic Metrics
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
praisonai "Explain quantum computing" --metrics
```
**Expected Output:**
```
Metrics enabled - will display token usage and costs
╭─ Agent Info ─────────────────────────────────────────────────────────────────╮
│ 👤 Agent: DirectAgent │
│ Role: Assistant │
╰──────────────────────────────────────────────────────────────────────────────╯
╭────────────────────────────────── Response ──────────────────────────────────╮
│ Quantum computing is a type of computation that harnesses quantum mechanical │
│ phenomena like superposition and entanglement... │
╰──────────────────────────────────────────────────────────────────────────────╯
📊 Metrics:
┌─────────────────────┬──────────────┐
│ Metric │ Value │
├─────────────────────┼──────────────┤
│ Model │ gpt-4o-mini │
│ Prompt Tokens │ 45 │
│ Completion Tokens │ 312 │
│ Total Tokens │ 357 │
│ Estimated Cost │ $0.0021 │
└─────────────────────┴──────────────┘
```
### Combine with Other Features
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
# Metrics with planning mode
praisonai "Complex analysis task" --metrics --planning
# Metrics with guardrail (shows combined usage)
praisonai "Generate code" --metrics --guardrail "Include tests"
# Metrics with router (shows selected model)
praisonai "Simple question" --metrics --router
```
## Metrics Displayed
| Metric | Description |
| - | - |
| **Model** | The LLM model used for the task |
| **Prompt Tokens** | Tokens in the input/prompt |
| **Completion Tokens** | Tokens in the response |
| **Total Tokens** | Sum of prompt + completion tokens |
| **Estimated Cost** | Approximate cost based on model pricing |
## Use Cases
### Cost Monitoring
Track costs across different prompts:
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
# Short prompt
praisonai "What is 2+2?" --metrics
# Expected: ~50 tokens, ~$0.0001
# Long prompt
praisonai "Write a detailed analysis of AI trends in 2025" --metrics
# Expected: ~2000 tokens, ~$0.012
```
### Model Comparison
Compare token usage across models:
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
# GPT-4o-mini (cheaper)
praisonai "Explain AI" --metrics --llm openai/gpt-4o-mini
# GPT-4o (more capable)
praisonai "Explain AI" --metrics --llm openai/gpt-4o
# Claude (different pricing)
praisonai "Explain AI" --metrics --llm anthropic/claude-3-haiku-20240307
```
### Planning Mode Metrics
See total tokens across all planning steps:
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
praisonai "Research and write a report" --metrics --planning
```
**Expected Output:**
```
📊 Metrics (Planning Mode):
┌─────────────────────┬──────────────┐
│ Metric │ Value │
├─────────────────────┼──────────────┤
│ Planning Tokens │ 523 │
│ Execution Tokens │ 1,847 │
│ Total Tokens │ 2,370 │
│ Estimated Cost │ $0.0142 │
└─────────────────────┴──────────────┘
```
## YAML Team Runs
`--metrics` and `--metrics-json` also work for `framework: praisonai` YAML team runs, with one row per agent.
```bash theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
praisonai agents.yaml --trust --metrics
```
```text theme={"theme":{"light":"vitesse-light","dark":"vitesse-dark"}}
Agent Metrics (model: openai/gpt-4o-mini)
┌──────────┬───────┬────────┬───────┬───────┬──────────┐
│ Agent │ Input │ Output │ Total │ Calls │ Time (s) │
├──────────┼───────┼────────┼───────┼───────┼──────────┤
│ Analyst │ 10 │ 5 │ 15 │ 1 │ 0.12 │
│ Writer │ 10 │ 5 │ 15 │ 1 │ 0.11 │
│ TOTAL │ 20 │ 10 │ 30 │ 2 │ 0.23 │
└──────────┴───────┴────────┴───────┴───────┴──────────┘
```
Use `--metrics-json` for the same data as JSON on stdout. See [Headless YAML Runs](/docs/features/headless-yaml-runs) for the JSON schema and exit codes.
## Cost Estimation
Cost estimates are approximate and based on publicly available pricing. Actual costs may vary based on your API plan.
### Typical Costs by Model
| Model | Input (per 1M tokens) | Output (per 1M tokens) |
| - | - | - |
| gpt-4o-mini | \$0.15 | \$0.60 |
| gpt-4o | \$2.50 | \$10.00 |
| claude-3-haiku | \$0.25 | \$1.25 |
| claude-3-sonnet | \$3.00 | \$15.00 |
## Best Practices
Use `--metrics` during development to optimize prompts and reduce costs before production deployment.
Monitor token counts to identify verbose prompts that can be shortened
Use metrics to compare cost/quality tradeoffs between models
Track cumulative costs across multiple runs for budget planning
High token counts may indicate prompt issues or infinite loops
For cross-session aggregate reporting — rolling up token and cost totals by day, model, or project — see [Usage](/docs/cli/usage).
## Related
* [Usage](/docs/cli/usage)
* [Telemetry CLI](/docs/cli/telemetry)
* [Router CLI](/docs/cli/router)
* [Models](/docs/models)
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.